publications
Publications in reverse chronological order. For a full list, please check my google scholar.
2026
-
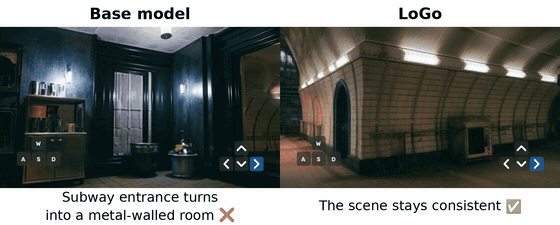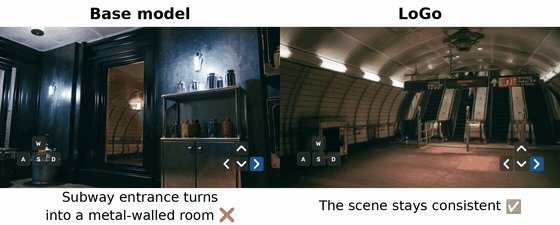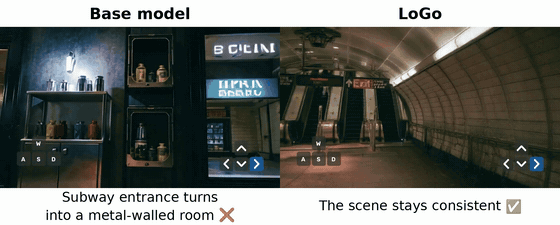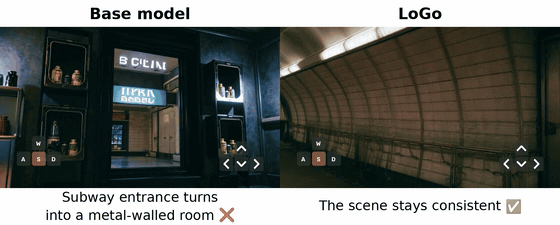 LoGo: Local-Global Rewards for Consistent Long-Horizon Video GenerationarXiv preprint, 2026TL;DR: A single scalar reward cannot say which part of a generated video drifted. We add a spatially localized reward next to the global one, so post-training knows where the inconsistency is and keeps scenes stable as the camera moves.
-
 World Tracing: Pixel-Aligned Geometry Beyond the VisibleIn NeurIPS, 2026 (Spotlight)TL;DR: Depth estimators stop at the visible surface, while image-to-3D models drift away from the input. We predict an ordered stack of 3D points per pixel to get geometry that stays faithful to the image and keeps going behind it.
-
 Atlas: A World Model for Spatial IntelligenceWorld Labs Blog, 2026TL;DR: An omni world model that natively handles text, images, video, and 3D, spanning generation, reconstruction, and simulation.


2025
-
 Marble: A Multimodal World ModelWorld Labs Blog, 2025TL;DR: Announcing Marble, our multimodal world model, available to all users.
-
 RTFM: A Real-Time Frame ModelWorld Labs Blog, 2025TL;DR: A research preview of a generative world model that renders video in real time.
-
 Generating Bigger and Better WorldsWorld Labs Blog, 2025TL;DR: Bigger, more detailed worlds with better geometry and style consistency, in limited beta.


2024
-
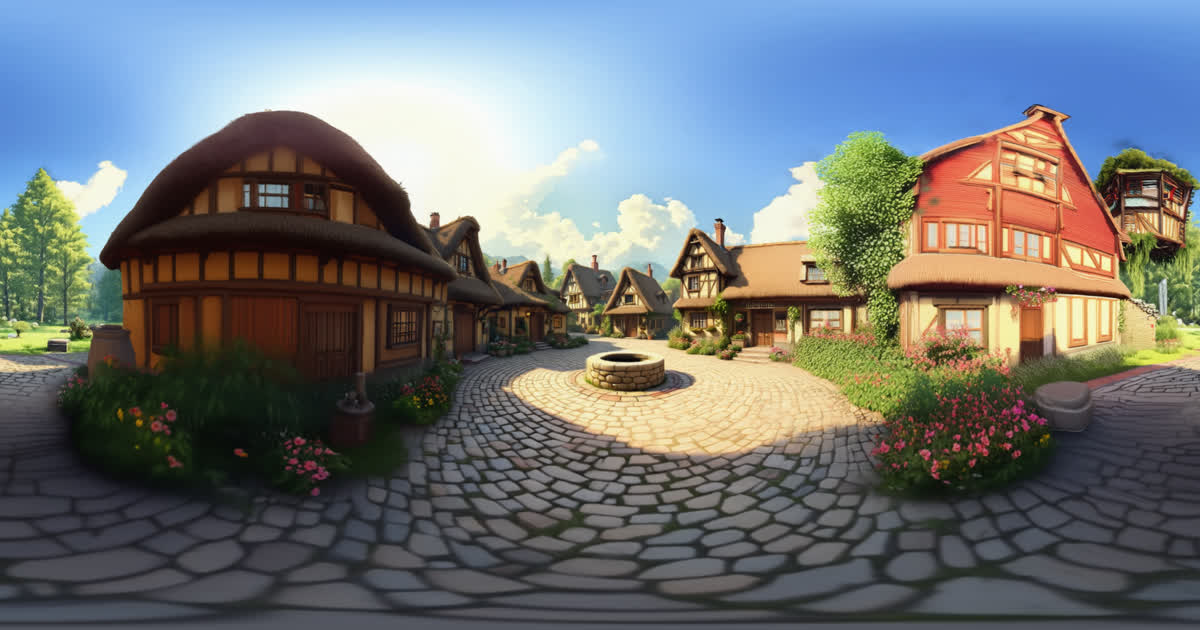 Generating WorldsWorld Labs Blog, 2024TL;DR: Progress toward persistent, navigable 3D worlds you can explore in your browser.


2023
-
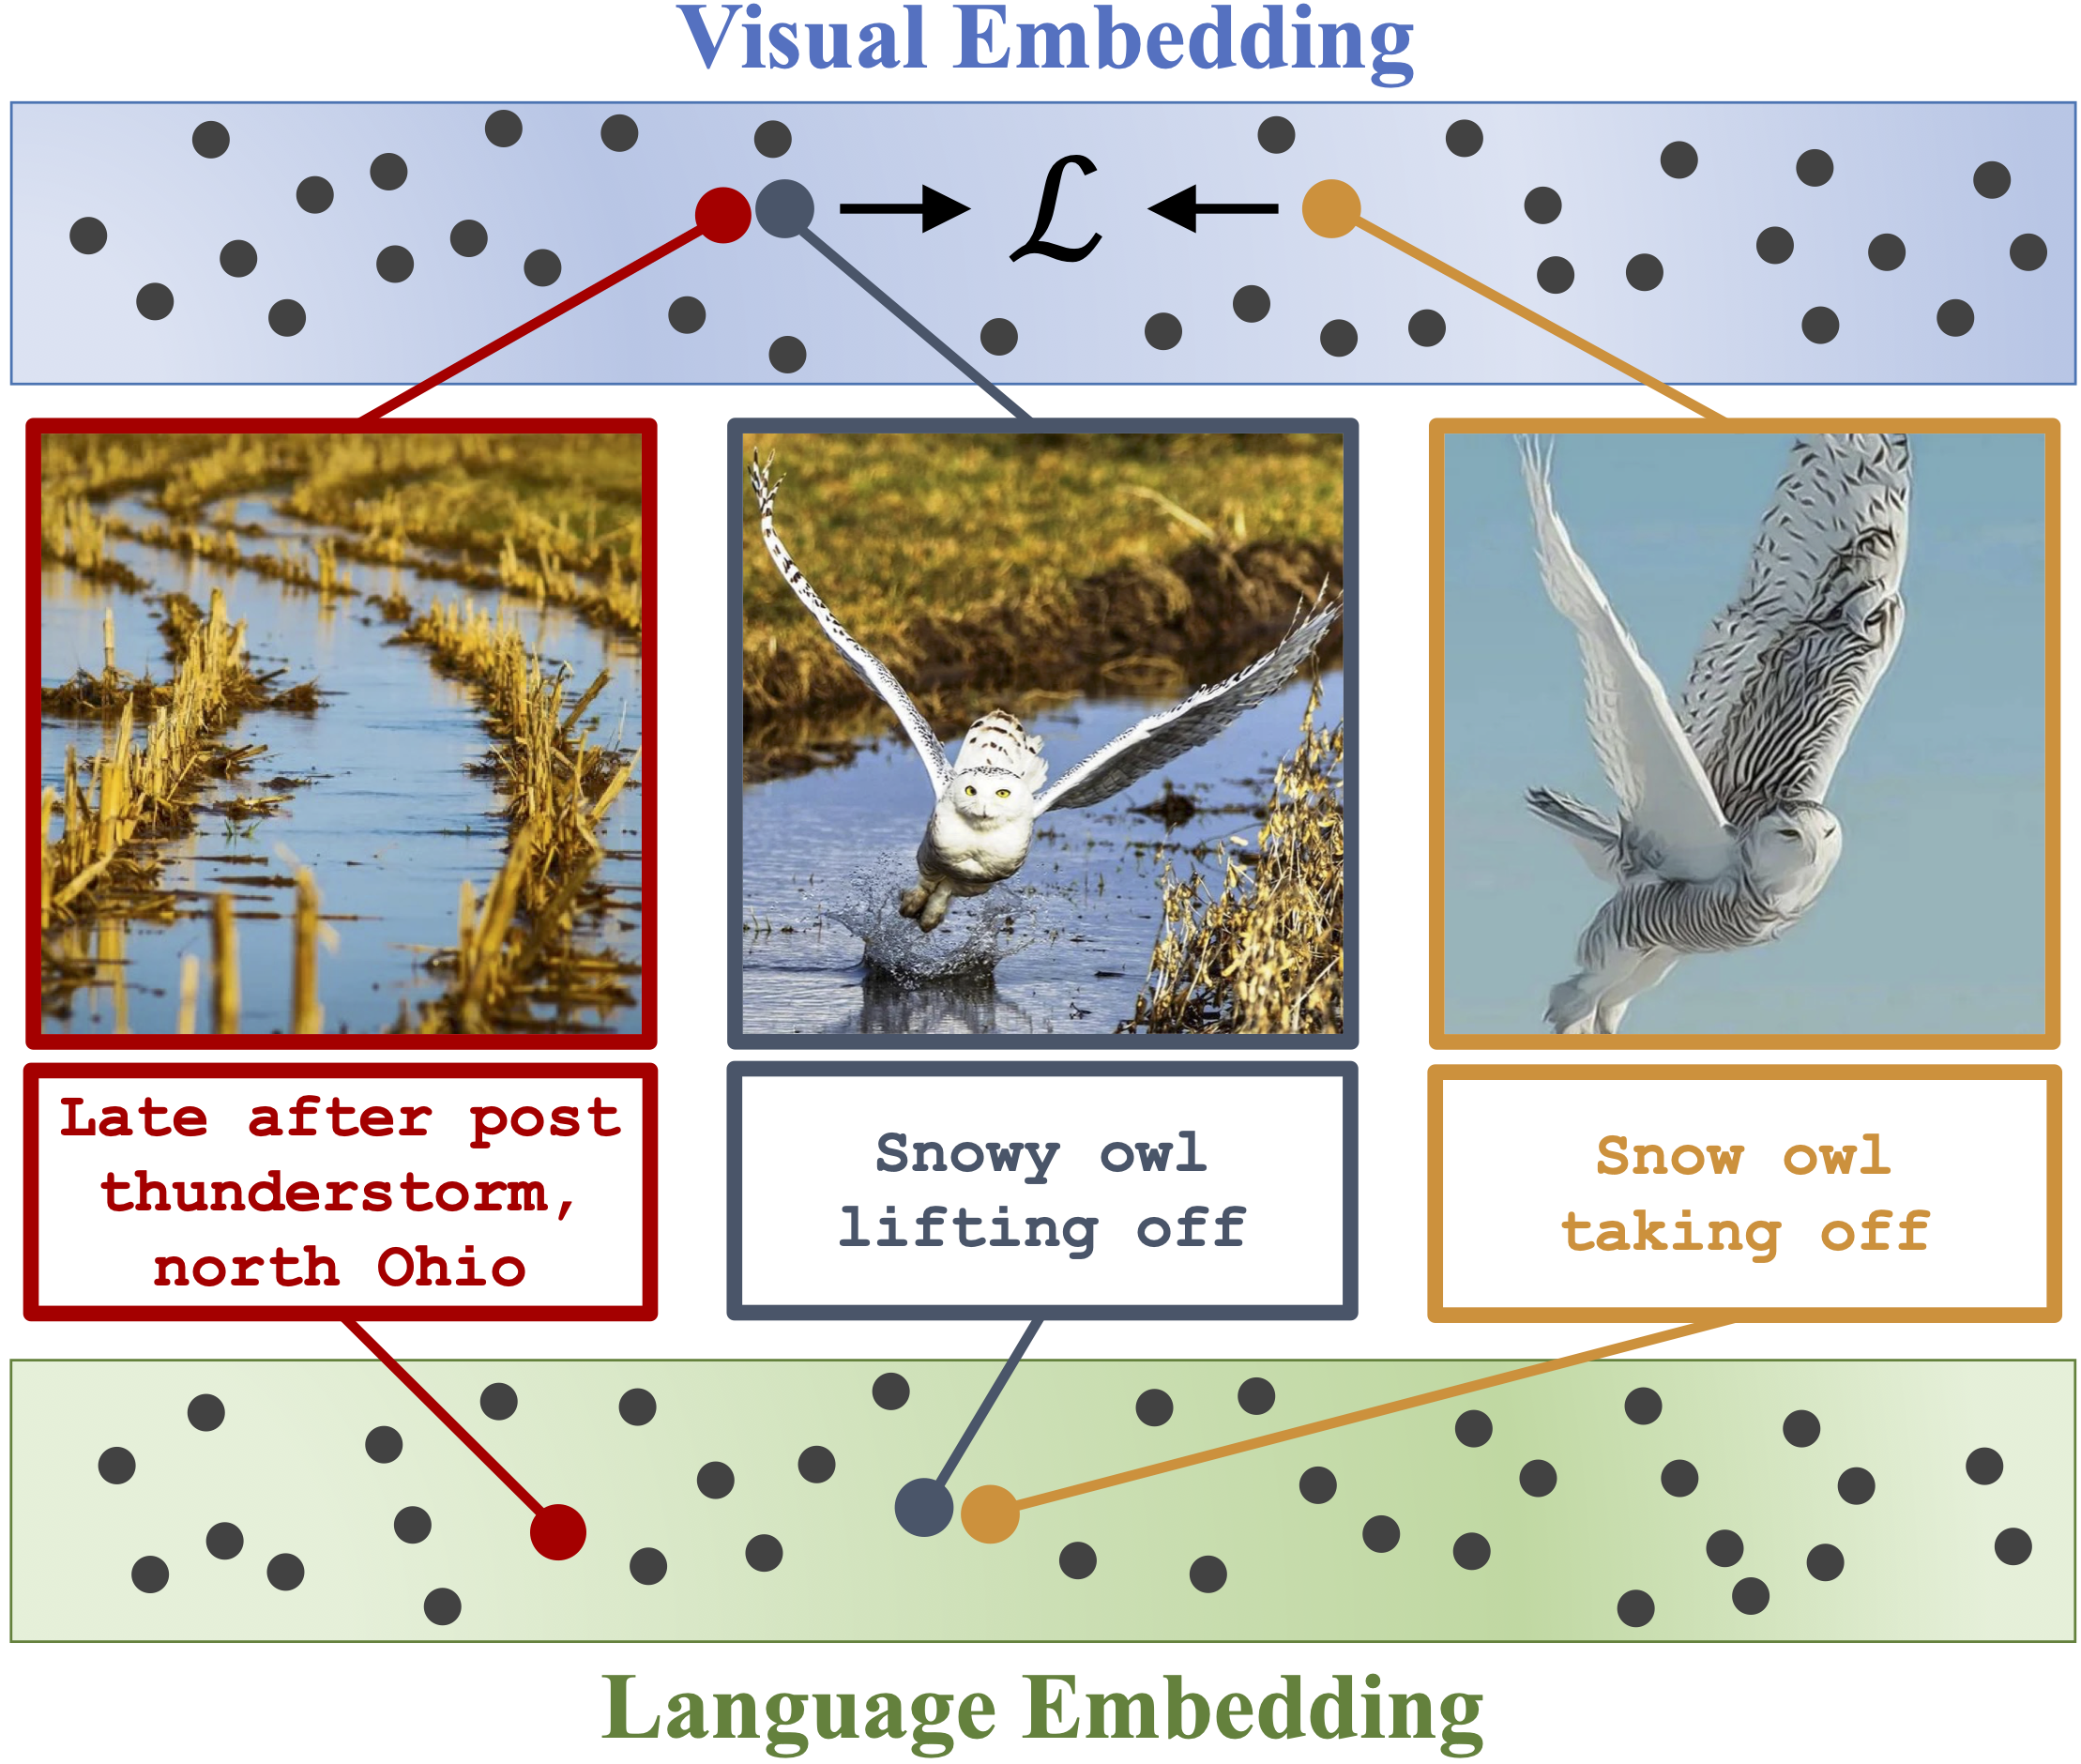 Learning Visual Representations via Language-Guided SamplingIn CVPR, 2023TL;DR: A picture is worth a thousand words, but a caption can describe a thousand images. We use language models to find image pairs with similar captions, and use them for stronger contrastive learning.
-
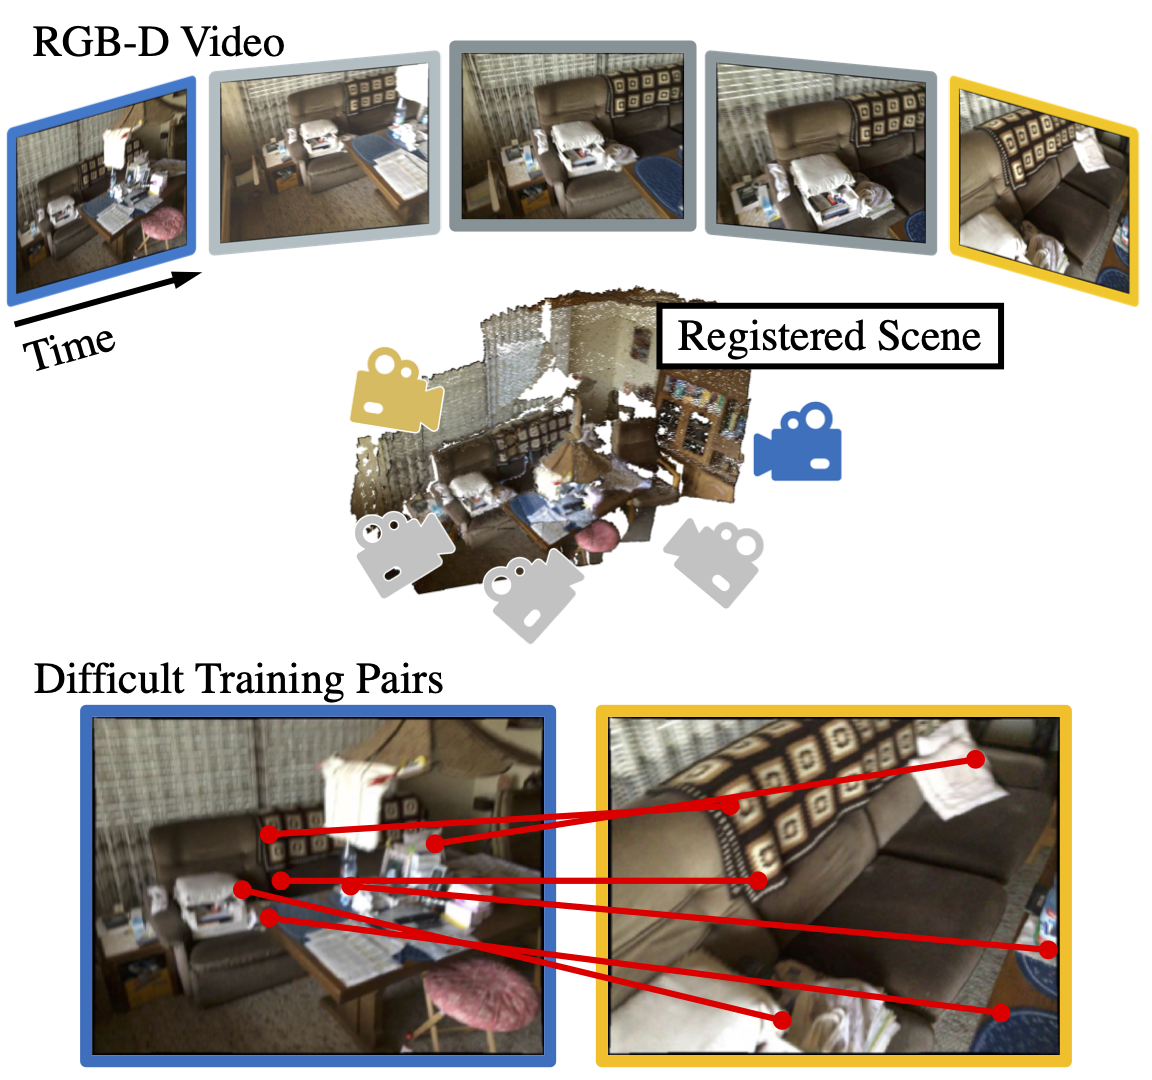 Self-Supervised Correspondence Estimation via Multiview RegistrationIn WACV, 2023TL;DR: Self-supervised correspondence estimation struggles with wide-baseline images. We use multiview registration and SE(3) transformation synchronization to leverage long-term consistency in RGB-D video


2021
-
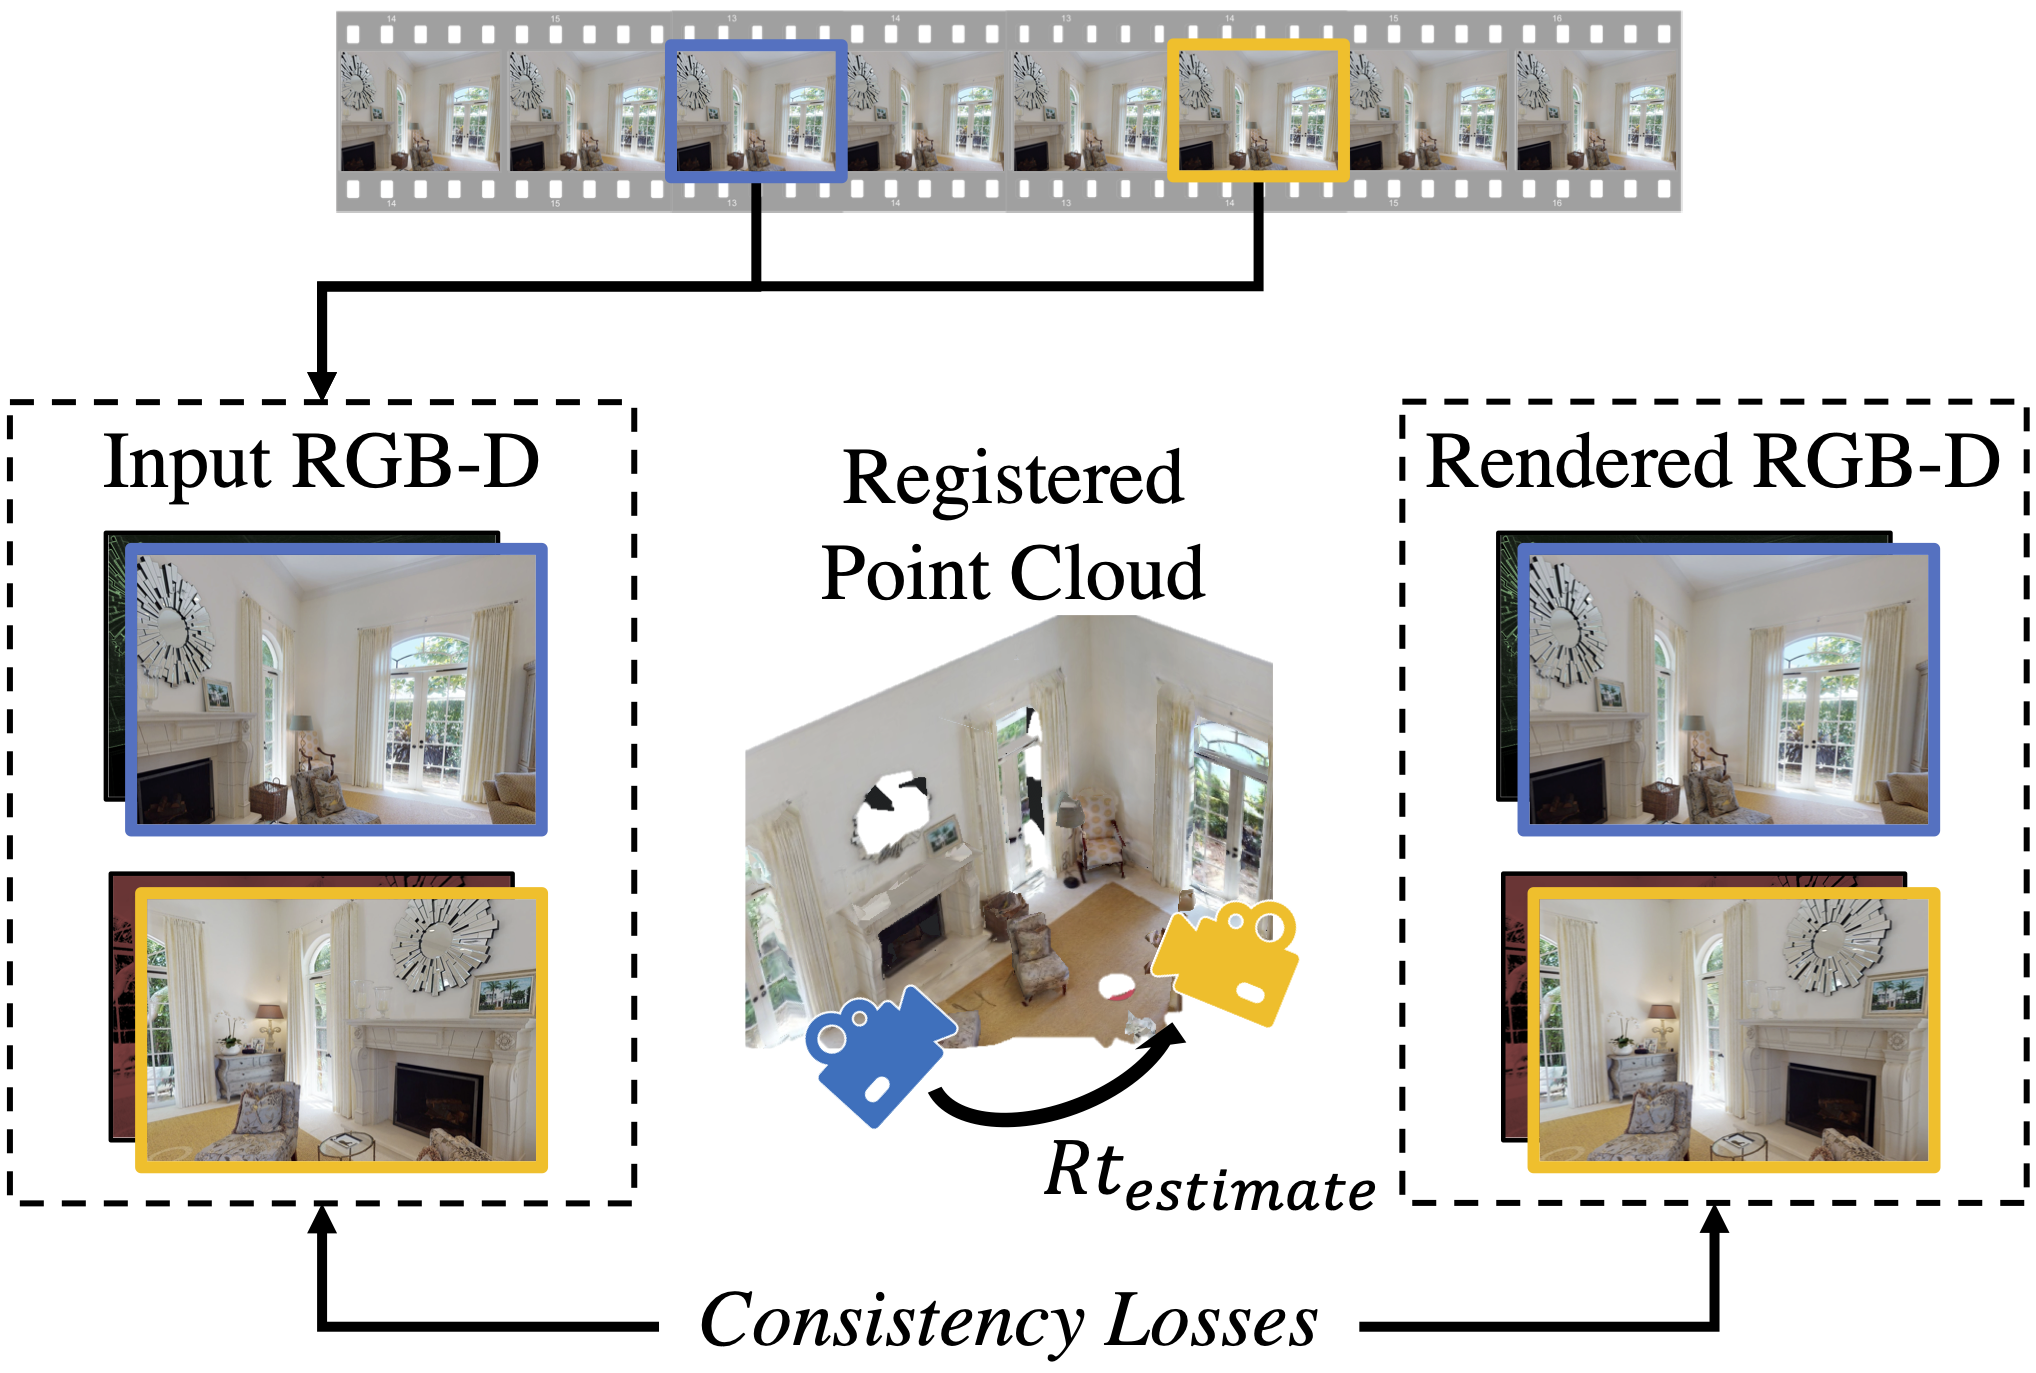 UnsupervisedR&R: Unsupervised Point Cloud Registration via Differentiable RenderingIn CVPR, 2021 (Oral)TL;DR: Can we learn point cloud registration from RGB-D video? We propose a register and render approach that learns via minimizing photometric and geometric losses between close-by frames.


2020
-
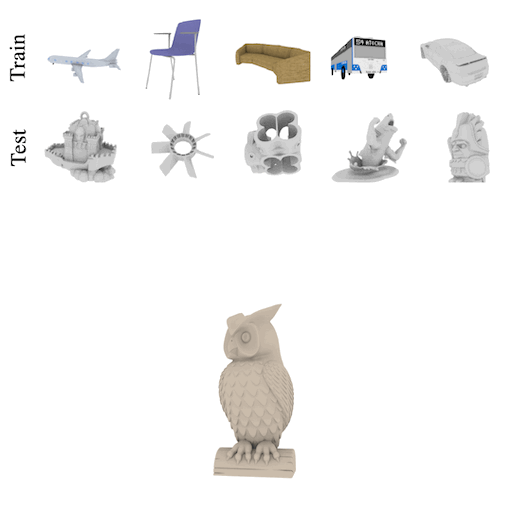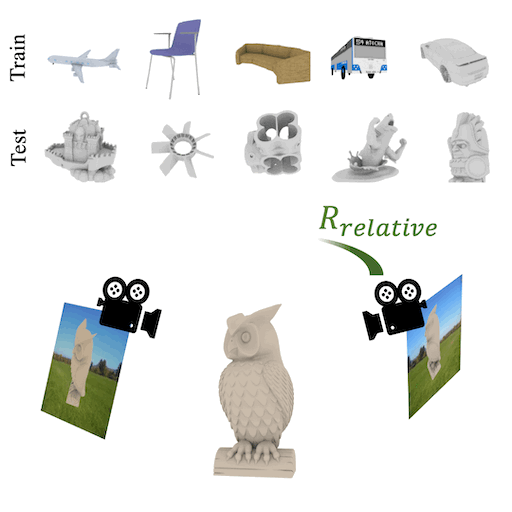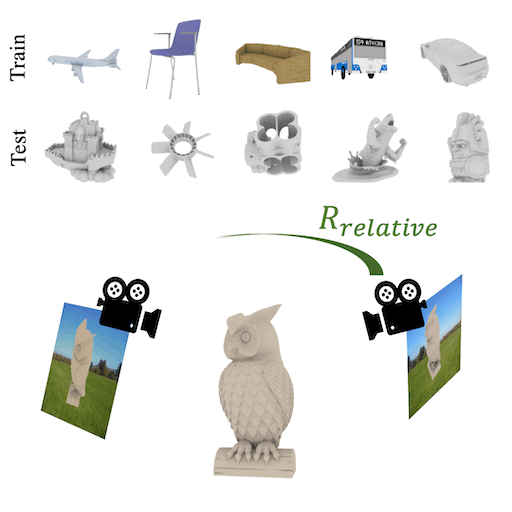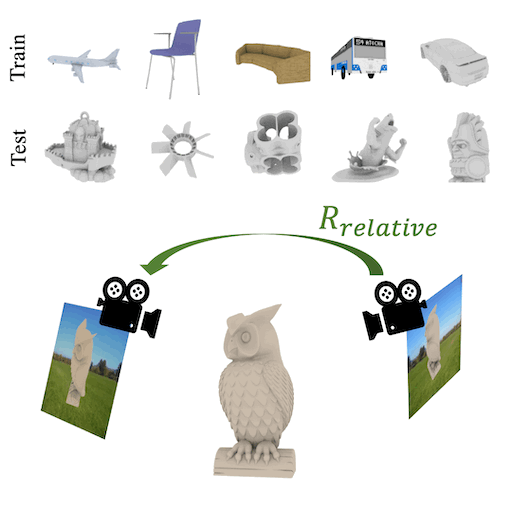 Novel Object Viewpoint Estimation through Reconstruction AlignmentIn CVPR, 2020TL;DR: Humans can not help but see 3D structure of novel objects, so aligning their viewpoints becomes very easy. We propose a reconstruct-and-align approach for novelobject viewpoint estimation.

2016
-
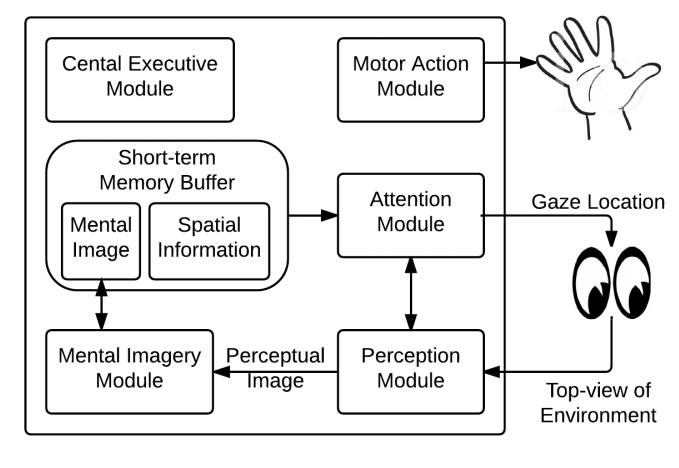 A Computational Exploration of Problem-Solving Strategies and Gaze Behaviors on the Block Design Task.In CogSci, 2016TL;DR: We present a computational architecture to model problem-solving strategies on the block design task. We generate detailed behavioral predictions and analyze cross-strategy error patterns.
-
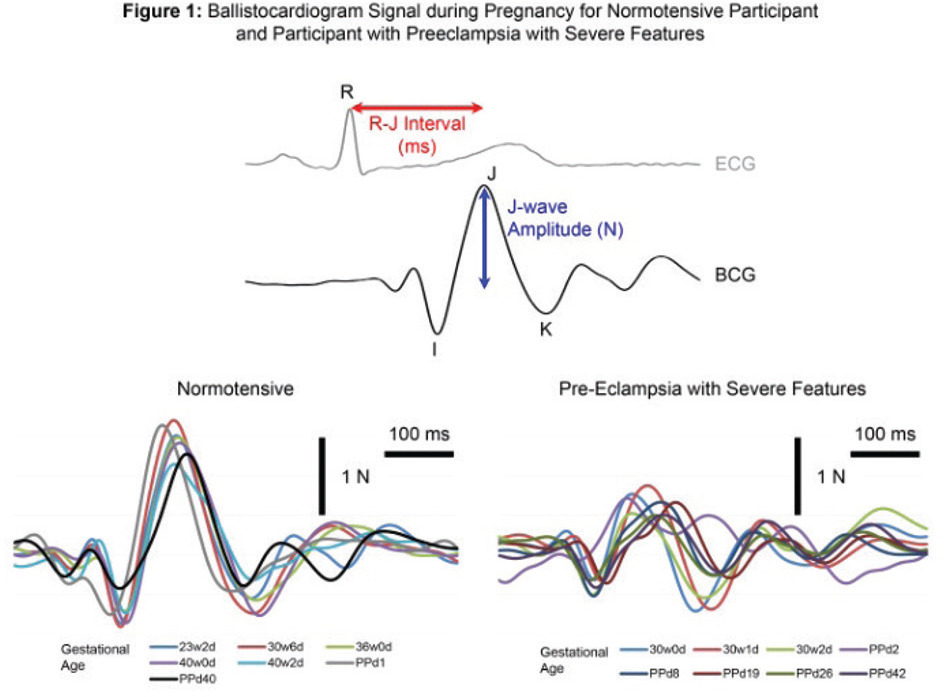 A Pilot Study of a Modified Bathroom Scale To Monitor Cardiovascular Hemodynamic in PregnancyJournal of the American College of Cardiology, 2016TL;DR: We use ballistocardiogram measurements extracted from a modified bathroom scale to analyze maternal cardiovascular adaptation during pregnancy for low-cost detection of preeclampsia.


